

Advanced voice settings
The Advanced settings page controls voice-specific configuration that goes beyond basic voice selection. Open it from the Advanced settings link in the top-right corner of the Voice page.
The page has three tabs: Model, Call, and Speech.
Model
Voice mode
Choose between two architectures for your voice agent:
Language model
Select the LLM that powers your voice agent.
Choose the LLM for voice conversations. PolyAI’s Raven models are recommended for voice – they are designed for conversational AI and deliver the most natural, grounded responses.
Controls response variability. Lower values (toward Deterministic) produce more consistent, predictable responses. Higher values (toward Creative) produce more varied output. Default is 0.4.
Recommended for voice: PolyAI’s Raven 3.5 is designed for conversational AI. It produces concise, natural responses without needing example utterances in your prompts — just add raw information and Raven converts it into conversational speech. Raven 3.5 supports 24+ languages, delivers sub-300ms latency, and includes auto-reasoning, out-of-domain detection, and built-in safety.
For a full list of available models, see the Model page.
Speech recognition
Choose the primary transcription engine and target language for your voice agent.
Select the ASR model used to transcribe caller speech. The model you choose affects transcription accuracy, latency, and language support.
Turn-taking
Control when the agent starts speaking after the caller stops.
How long to wait (in milliseconds) after the caller stops speaking before the agent begins its response. Fast (200ms) responds quickly but may cut off pauses. Tolerant (1000ms) waits longer through pauses but adds latency.
AI-coustics
Removes background noise and enhances audio quality. Enable this for callers in noisy environments.
Call
Barge-in
Allow callers to interrupt the agent mid-utterance. When enabled, the agent stops speaking as soon as it detects caller speech, shortening VAD time and reducing response latency.
Toggle on to let callers interrupt the agent mid-sentence.
When enabled, barge-in is active from the very first agent utterance (including the greeting). When disabled, barge-in activates after the first turn completes.
Limit how many times a caller can interrupt per call. Set to 0 for unlimited.
How barge-in works
When barge-in is enabled:
- The agent begins speaking its response.
- If the caller starts talking, the agent stops its current utterance and begins listening.
- The agent processes the caller’s input and responds as a new turn.
This also applies to delay control responses – if the caller speaks during a filler phrase, the delay sequence is interrupted.
When to use barge-in
Barge-in works well for:
- FAQ-heavy agents where callers may already know what they need
- Long agent responses where the caller wants to redirect the conversation
- Fast interaction styles where responsiveness is a priority
When to disable barge-in
Consider disabling barge-in (globally or per flow/step) when:
- The agent is executing a function with external side effects (bookings, payments, form submissions) – the caller may interrupt after the action completes but before hearing the confirmation
- The agent must deliver a mandatory disclosure or disclaimer that cannot be skipped
- The environment is noisy, causing false barge-in triggers from background sounds
Per-flow and per-step overrides
You can configure barge-in at a granular level using the experimental JSON config. This lets you enable barge-in globally while disabling it for specific flows or steps where interruption would be problematic.
Overrides follow a precedence order: step > flow > global. For example, you can have barge-in off globally, enabled for a specific flow, and disabled again for a sensitive step within that flow.
Barge-in behavior cannot be fully tested in the chat panel. Always verify with a real phone call.
Filler phrases
Configure brief sounds or words the agent uses while processing the user’s input — “One moment…”, “Just a second…”, etc. These fill the gap between the caller finishing and the agent responding, preventing awkward silence.
Toggle on to enable filler phrases during processing delays.
When enabled, the agent picks randomly from the configured phrases instead of cycling in order.
How many seconds to wait before the first filler phrase plays.
How many seconds between subsequent filler phrases if the agent is still processing.
Customer satisfaction survey (CSAT)
Enable to collect customer feedback during voice calls. Additional options appear once enabled.
When enabled, the agent can route callers into a CSAT survey flow at the end of the conversation. For full configuration details — survey questions, scoring, and dashboard integration — see CSAT surveys.
Speech
Safety filters
Safety filters are configured on a per-channel basis. The voice channel has its own safety filter settings, separate from the chat channel and the project-wide defaults. See Safety filters for the full reference on categories, severity levels, and how filters interact with Guardrails.
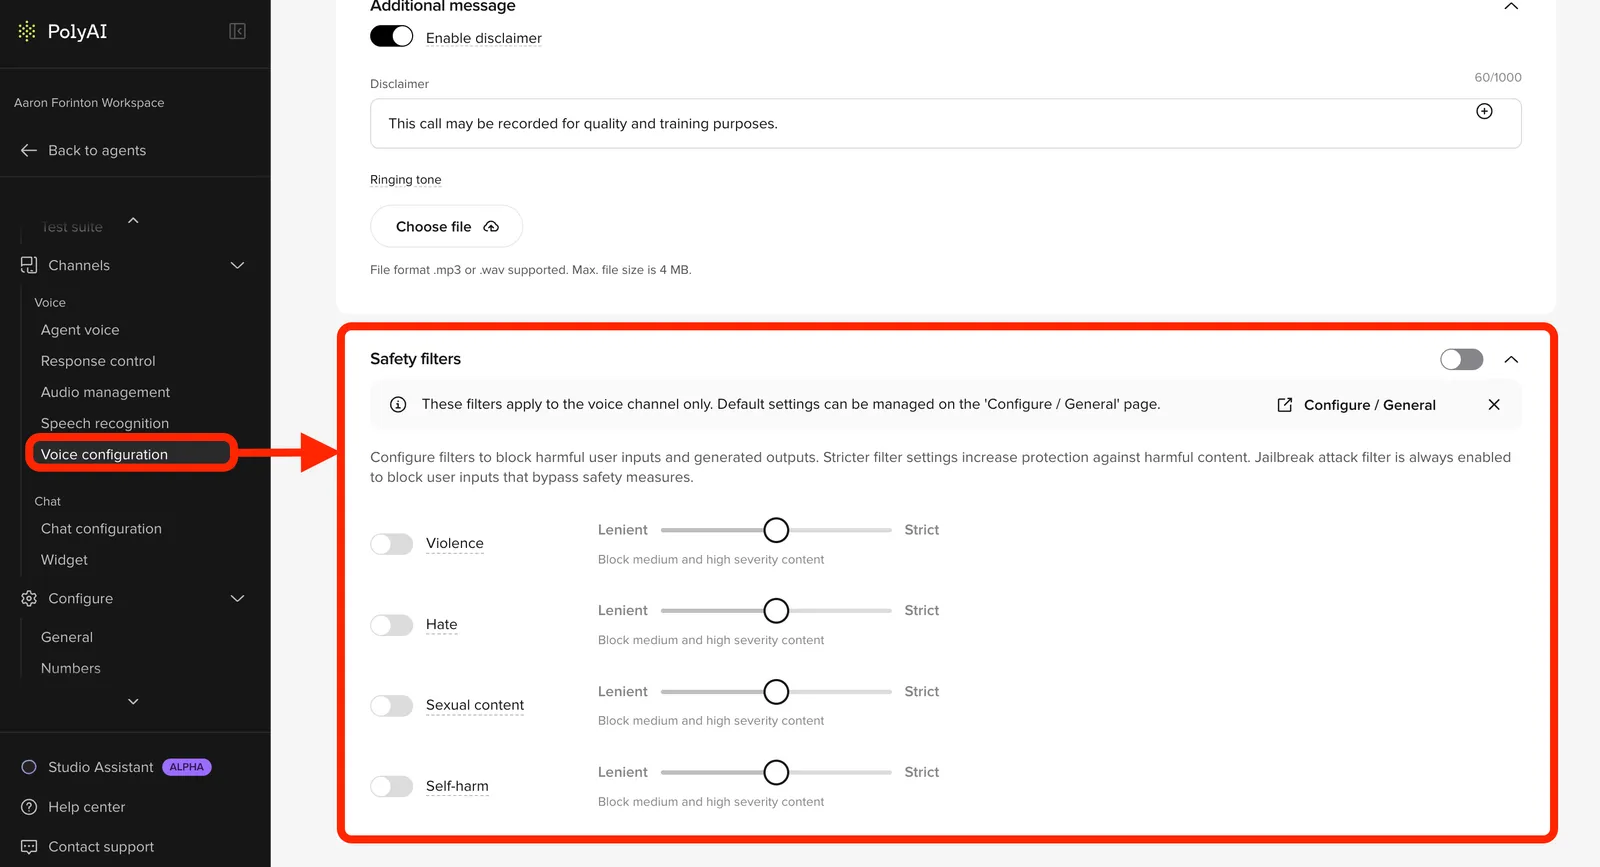
When enabled, applies content filtering to voice responses. These filters apply to the voice channel only. Default settings can be managed on the Behavior page.
When safety filters are enabled, adjust the strictness for each category using the sliders:
The jailbreak attack filter is always enabled and cannot be turned off.
More lenient settings allow a wider range of content through. Review your use case and compliance requirements when adjusting these settings.
Keyphrases
Keyphrase boosting improves ASR recognition of domain-specific terms like product names, locations, or specialized vocabulary. It biases the ASR model toward recognizing specific words during transcription.
Biasing the ASR can cause unwanted side effects. Adding too many keyphrases or setting bias too high may cause the model to over-correct natural speech. For example, boosting the word flimsy at Maximum strength could cause unrelated words like Lindsay to be transcribed as flimsy. Always test thoroughly in sandbox before deploying changes to production.
Configuring keyphrases
- Open the Keyphrases section on the Speech tab.
- Add, edit, or remove keyphrases.
- Adjust the bias strength for each keyphrase using the slider.
- Save your changes. Updated keyphrases are applied immediately.
Bias strength levels
Maximum bias does not always produce better results. In some cases it can cause the model to misrecognize unrelated words. Start with Default or Boosted and only escalate to Maximum after testing confirms it is needed.
Example keyphrases
Keyphrase boosting and ASR biasing are the same mechanism. Keyphrase boosting is the global level of ASR biasing – it applies to every turn of the conversation. ASR biasing also has per-step and dynamic levels for more targeted control. See ASR biasing in flows and ASR biasing from functions.
Global vs. per-step vs. dynamic biasing
The Speech tab configures global keyphrase boosting, which applies to every turn of the conversation. Two additional levels of biasing are available for more targeted control:
- Per-step biasing – configure ASR biasing on individual flow steps for contextual precision (e.g. biasing for doctor names only during a name-collection step). See ASR biasing in flows.
- Dynamic biasing from functions – set biasing at runtime using
conv.set_asr_biasing()when you need to bias toward values retrieved from an API or database. See ASR biasing from functions.
Precedence rules: When multiple levels of biasing are active, they are merged with the following priority (highest first):
- Dynamic – biasing set via
conv.set_asr_biasing()in functions - Per-step – biasing configured on individual flow steps
- Global – biasing configured on the Speech tab
If the same phrase appears at multiple levels, the highest-priority setting takes precedence.
Transcript corrections
Fix common ASR misinterpretations using string matching and regex patterns. Unlike keyphrases, transcript corrections run after the ASR model has produced a transcript – they replace text in the output rather than influencing what the model hears.
Transcript corrections can match broadly and introduce errors if the pattern is too wide. A correction like blue star → BlueStar could also fire on legitimate uses of “blue star” in other contexts. Use specific regex patterns and test corrections against a range of real transcripts before deploying.
Configuring transcript corrections
- Open the Transcript corrections section on the Speech tab.
- Click Correction to create a new rule.
- Give the correction a name (must be unique) and optional description.
- Add one or more regex rules within the correction:
- Replacement type: Full transcript (replaces the entire transcript if matched exactly) or Partial transcript (replaces only the matching portion).
- Regex: the regular expression to match the misinterpreted phrase.
- Replacement: the correct term or phrase (leave empty to delete the matched text).
- Changes auto-save as you edit.
You can group multiple related regex rules under a single correction. For example, create a correction called “Brand names” containing rules for each brand your agent handles.
Example configurations
Verifying corrections are applied
- Open a conversation in Conversation Review.
- Enable the Transcript corrections layer in Conversation Diagnosis.
- Check each turn to see whether your correction was triggered.
If a correction is not firing as expected, compare the raw ASR transcript against your regex pattern. Common issues include unexpected whitespace, casing differences, or partial word boundaries.
Pronunciation
Control how your agent pronounces specific terms using the International Phonetic Alphabet (IPA) or SSML tags. Useful for brand names, proper nouns, and domain-specific vocabulary that TTS engines frequently mispronounce.
Pronunciation rules apply to voice agents only. For text-channel agents, this section can be skipped.
How it works
Pronunciation rules use regex patterns to match text in the agent’s response and replace it with IPA notation or SSML markup before it reaches the TTS engine. You can also use SSML such as <break>, <prosody>, and <emphasis> in the replacement string.
Multilingual pronunciation rules
For multilingual agents, pronunciation rules are organized by language. Each language has its own set of rules displayed as separate collapsible cards. Rules within a language card only apply to responses in that language.
To add a rule for a specific language:
- Expand the language card.
- Add the regex pattern and replacement.
- The rule automatically scopes to that language.
Rules with no language specified apply globally across all languages.
Rule evaluation order
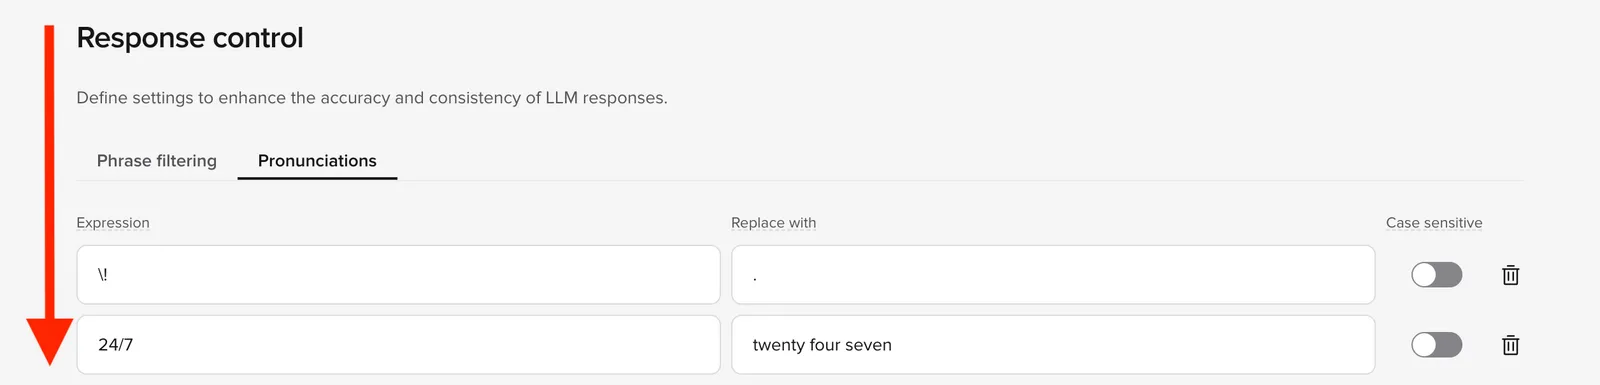
Pronunciation rules are evaluated from top to bottom. Each rule runs on the text produced by the rule above it. Because rules are applied sequentially, later rules can modify or override earlier transformations.
Common pronunciation patterns
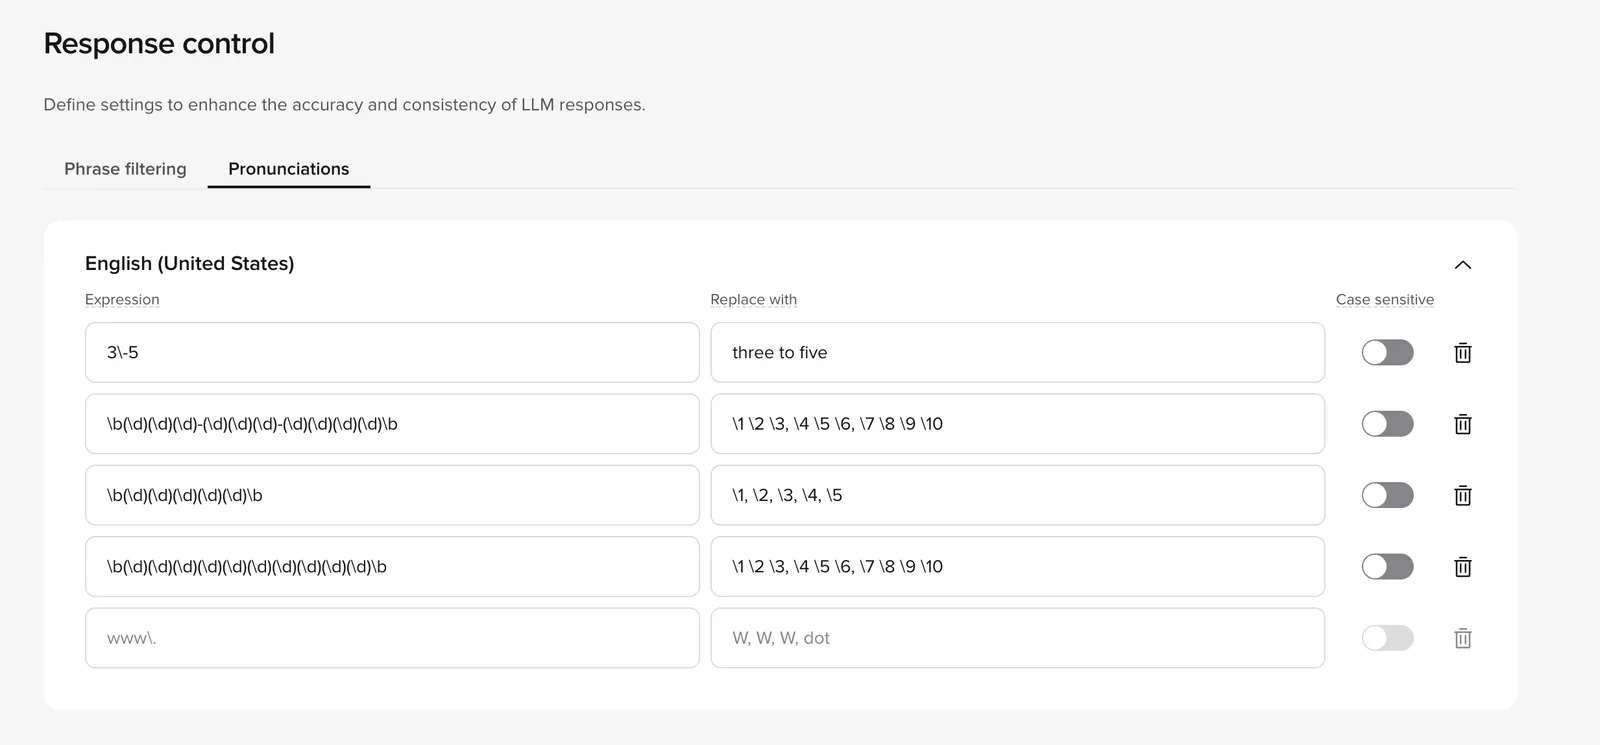
Simple text replacement
Replace a specific string with a spoken equivalent.
- Regex:
3\-5 - Replacement:
three to five
Read a phone number digit by digit
- Regex:
\b(\d)(\d)(\d)-(\d)(\d)(\d)-(\d)(\d)(\d)(\d)\b - Replacement:
\1 \2 \3, \4 \5 \6, \7 \8 \9 \10
Produces “six five one, three five nine, two nine two three” for 651-359-2923.
Read a zip code digit by digit
- Regex:
\b(\d)(\d)(\d)(\d)(\d)\b - Replacement:
\1, \2, \3, \4, \5
Make a URL speakable
- Regex:
www\. - Replacement:
W, W, W, dot
SSML pauses in phone numbers
- Regex:
\(?(\d{3})\)?[ -]?(\d{3})[ -]?(\d{4}) - Replacement:
\1 <break time="0.5s" /> \2 <break time="0.5s" /> \3
Handles multiple formats — (651) 359-2923, 651-359-2923, or 6513592923 — and inserts half-second pauses. See SSML breaks for more timing options.
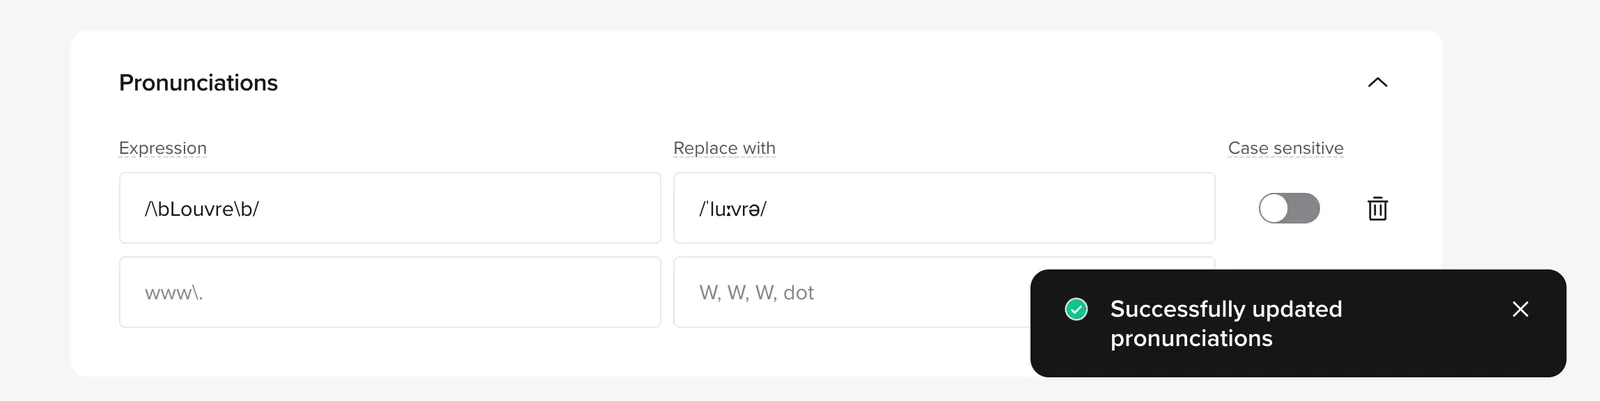
IPA correction
- Regex:
\bLouvre\b - Replacement:
/ˈluːvrə/ - Case sensitive:
FALSE
Stop keywords
When a response matches a stop keyword pattern, the system halts the response and logs the occurrence. Use stop keywords to catch sensitive content, remove unnecessary preambles, or enforce brand adherence.
Stop keyword fields
When a function is triggered by a stop keyword, caller input and LLM parameters are not passed to the function. The function runs without conversation context, so it should return a static response or handle the absence of context gracefully.
Creating a stop keyword
1. Create a function
2. Configure the keyword
3. Test
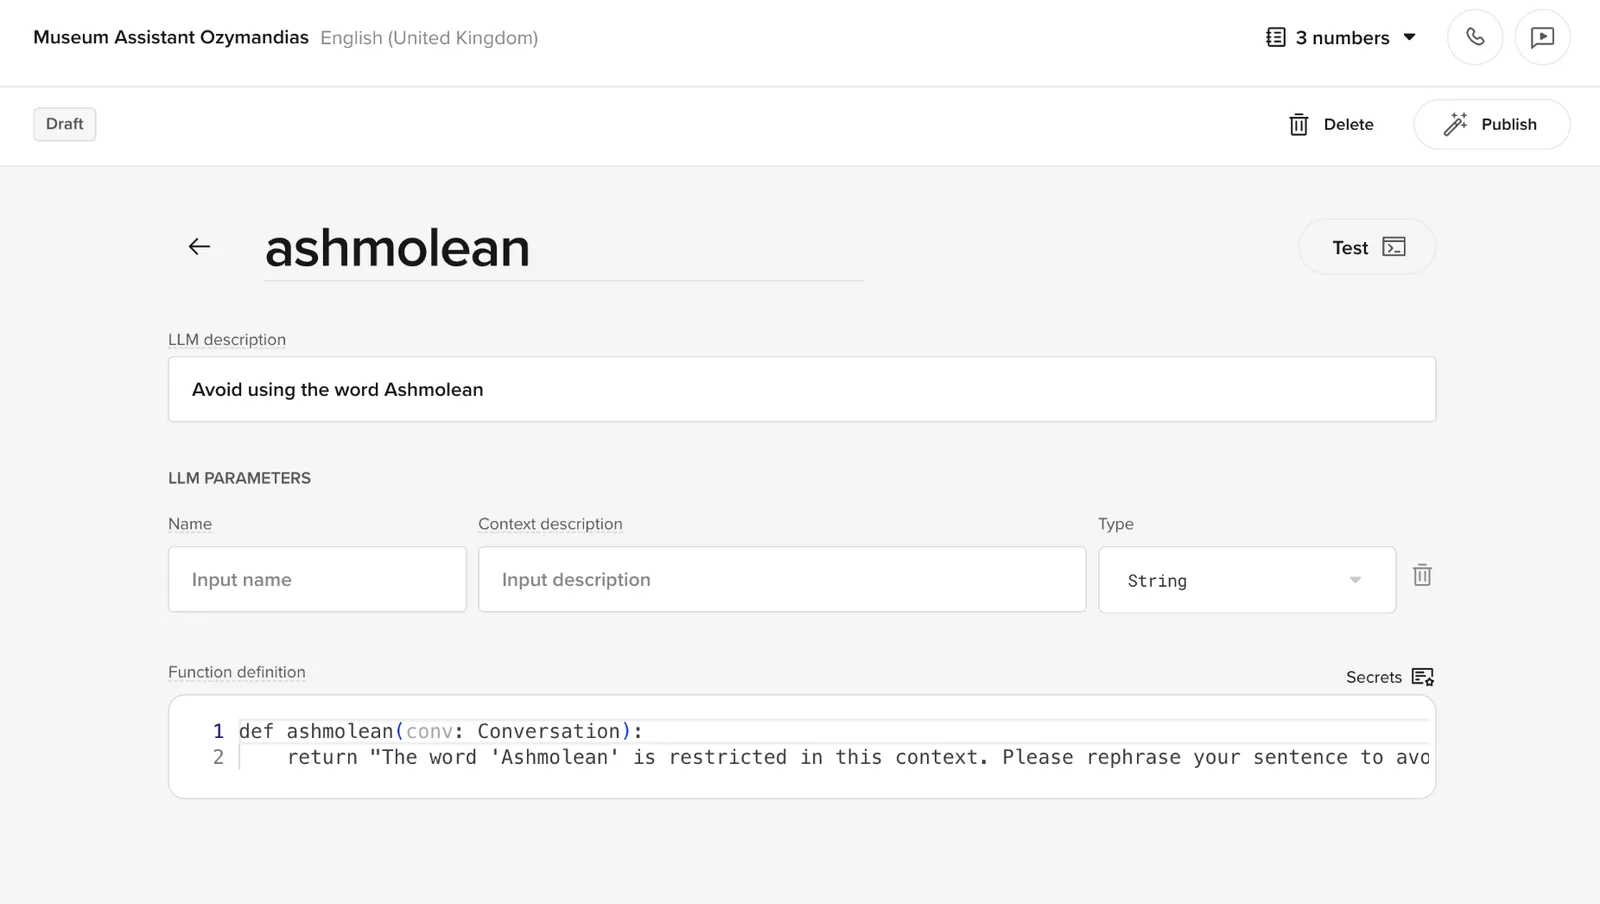
Go to Tools to define a custom function for handling stop keywords.
Example setup:
- Name: restricted_phrase
- Description: Respond when stop keywords are detected.
- Function definition:
Common use cases
Safety compliance
Prevent offensive or harmful language in user interactions.
Remove LLM preambles
LLMs often add unnecessary meta-explanations before executing an action. Stop keywords cut these off instantly.
Before: “Let’s start by gathering some information. Please hold on while I check your cancellation options. Here are your cancellation options.”
After: “Here are your cancellation options.”
Add a stop keyword in Voice > Advanced settings > Speech:
Brand adherence
Block responses with phrases outside approved messaging. Log matches for review in the Analytics Dashboard.
Use regex for complex patterns. See regex101.com for a testing tool.
Diacritics
If your agent operates in a language that uses diacritics – such as č, ć, š, ž, đ – additional configuration is required before keyphrases and transcript corrections will work correctly.
Diacritics and multilingual ASR configuration cannot be self-served. Contact your PolyAI representative before making changes – they will configure the correct ASR language model, language codes, and any necessary preprocessing for your target language.
Transcript corrections can help with minor post-processing (e.g. fixing Zeljko → Željko) once the correct ASR model is in place, but they are not a substitute for proper language configuration.
Environment behavior
Advanced voice settings follow the same branching behavior as other channel settings:
- Make changes in Sandbox for testing
- Promote to Pre-release for UAT
- Deploy to Live for production